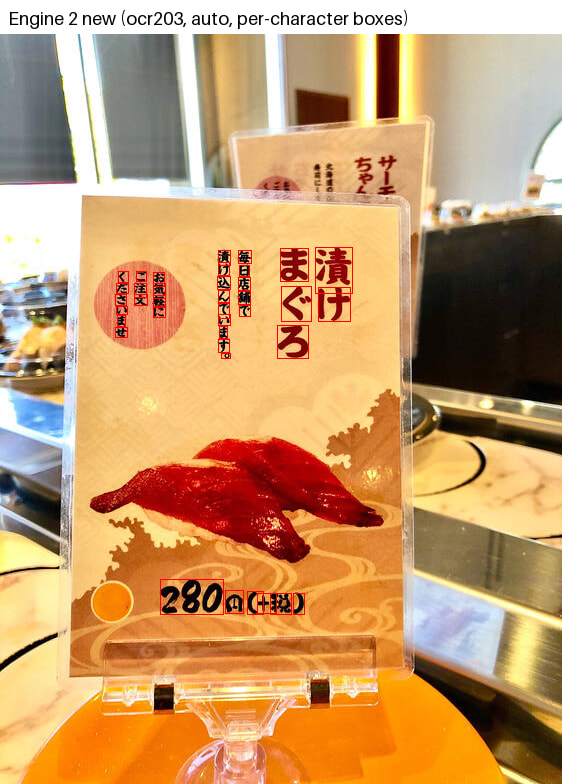
Thanks for the detailed report and the two test images. Today’s engine2 update fixes the bounding box issue that you reported.
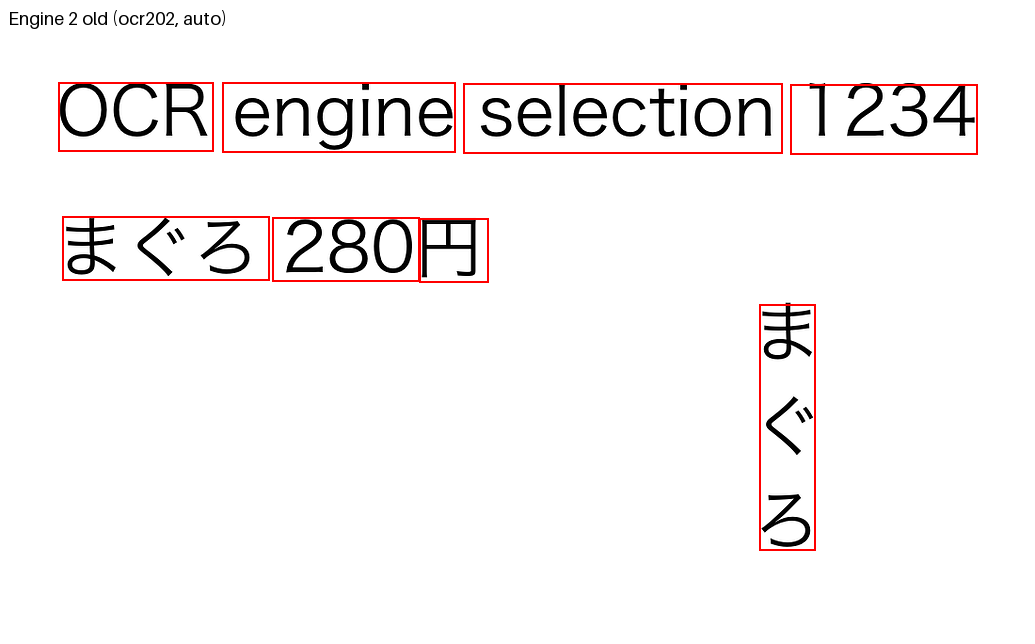
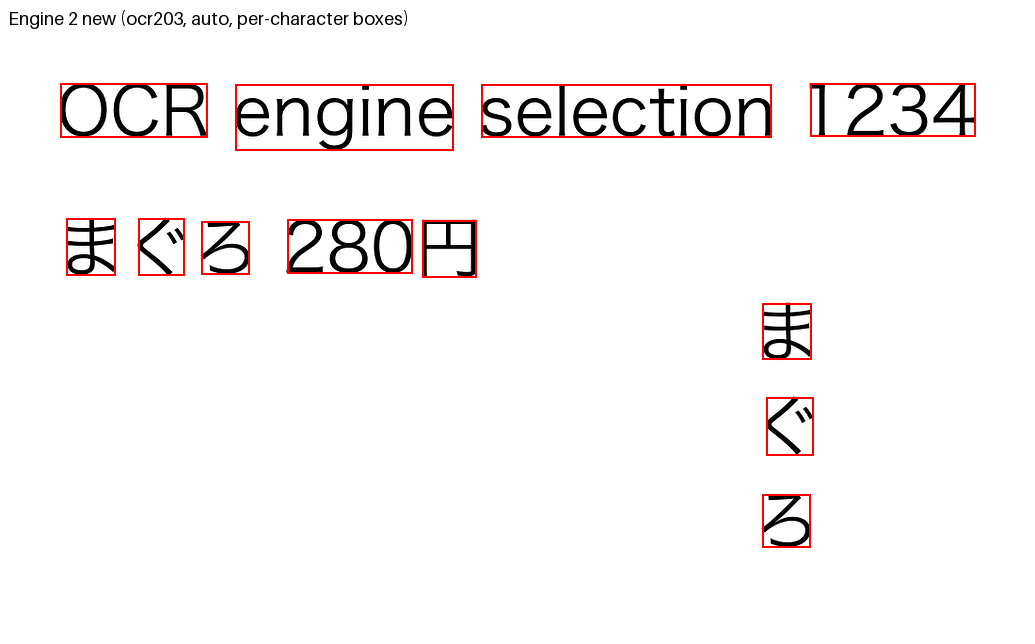
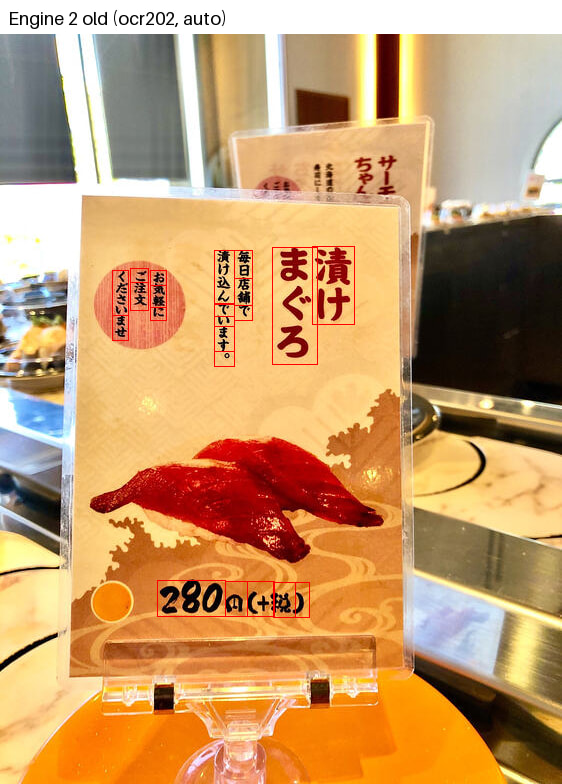
Engine 2 now returns one bounding box per Japanese character. Until now engine 2 grouped Japanese (and Chinese and Korean) text into “logical words” such as まぐろ or 毎日 and reported the line height as the box height. Engine 2 now reports every CJK character as its own word, and every box is fitted to the glyph ink, the way engine 1 does it. Digits and Latin words stay together as words (280 + 円, OCR + engine). The text output (ParsedText, LineText) is unchanged.
Please use language=auto for Japanese. With language=jpn, engine 2 uses a recognizer that only reads horizontal text, which is why your vertical menu card came back nearly empty. With auto, engine 2 reads vertical columns, mixed scripts and mixed languages, and in our comparison across 40 language samples it was as accurate as a specified language, so there is no quality reason to set the language for engine 2.
Rollout. The new boxes are live on the free endpoint now and will reach the PRO endpoints next week. Engine 2 keeps the same JSON structure, so no client change is needed; only the granularity of Words for CJK text changes.
If you have a sample where the new boxes still do not fit, please post it here and we will look at it.
Before update:
 After today’s update:
And for the Japanese menu:
Before update:
After today’s update: